llama.cpp, which runs models that accept images and text, has changed image tiling and size calculations for the LFM2 family. Prompt token counts and request times can rise or fall with image size, requiring evaluations and time budgets to be rechecked. The reference is the Python image processing code in the Transformers library.
3 key changes
Tiles are stretched. Large images are split into 512x512 tiles and a small full-image preview. Previously, most preserved aspect ratios with black padding; now all are stretched to fit the tile grid. In PR #30261 measurements with LFM2.5-VL-450M and a 1024x768 image, tile pixel values differing from Transformers fell from 97.5% to 0.
Layouts are calculated as in Python. Exact halves round to even, and floating-point precision is higher. Across widths and heights of 1~4096, 31,926 sizes had different preview sizes or tile grids; these now match the reference code. A 400x600 preview changes from 416x608 to 384x608, and the grid for 720x1600 changes from 2x5 to 2x4 tiles.
Only LFM2 code changed. The changes apply only to LFM2 preprocessing; other model paths remain unchanged. Tests now include 4 thumbnail sizes and 4 grids based on Transformers values. The previous code failed 6 of the 13 checks in these tests.
By the numbers
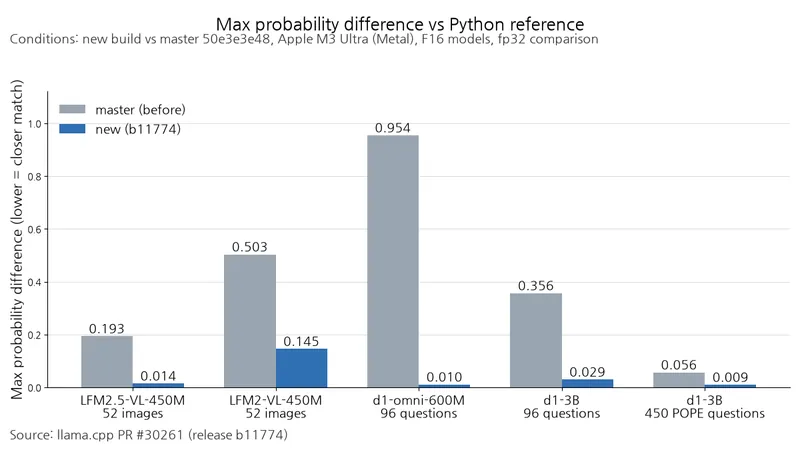
The author of PR #30261 compared master 50e3e3e48 and the patched version against the Python reference code. The two groups use different probability comparison targets and must be considered separately.
Table: Maximum probability differences and prompt length mismatches against the Python reference implementation for the LFM2 family
Conditions: PR #30261 measurements, master 50e3e3e48 versus the patched version, Apple M3 Ultra(Metal), F16 models, fp32 comparison. Based on the top 20 next tokens from Transformers.
Units: Probability differences as ratios; mismatch counts as items
| Model / test set | Maximum probability difference · master | Maximum probability difference · patched | Items with prompt length mismatches · master → patched |
|---|---|---|---|
| LFM2.5-VL-450M, 52 images | 0.193 | 0.014 | 14 → 0 |
| LFM2-VL-450M, 52 images | 0.503 | 0.145 | 14 → 0 |
Table: Maximum probability differences and prompt length mismatches against the Python reference implementation for the d1 family
Conditions: PR #30261 measurements, master 50e3e3e48 versus the patched version, Apple M3 Ultra(Metal), F16 models, fp32 comparison. Based on all answer candidates.
Units: Probability differences as ratios; mismatch counts as items
| Model / test set | Maximum probability difference · master | Maximum probability difference · patched | Items with prompt length mismatches · master → patched |
|---|---|---|---|
| d1-omni-600M, 96 questions | 0.954 | 0.010 | 42 → 0 |
| d1-3B, 96 questions | 0.356 | 0.029 | 36 → 6 |
| d1-3B, 450 POPE questions | 0.056 | 0.009 | 5 → 0 |
Prompt length mismatches disappeared in four of the five model/test combinations. The remaining probability difference for LFM2-VL-450M comes from using linear interpolation because the public mmproj lacks a resizing setting. A comparison specifying bicubic, as in the reference code, yielded 0.444 → 0.003.
In the measurements, token counts and request times moved in the same direction.
Table: Changes in prompt token counts and total request times by image size
Conditions: PR #30261 measurements, master 50e3e3e48 versus the patched version, F16, -np 1, H100 GPU(CUDA) and 30-core Xeon 8358(CPU).
Units: Token counts; request time changes in %
| Image | Prompt tokens · master → patched | CUDA·LFM2.5-VL | CUDA·d1-3B | CPU·LFM2.5-VL | CPU·d1-3B |
|---|---|---|---|---|---|
| 504x1120 | 2817 → 761 | -65.0% | -69.4% | -73.6% | -72.6% |
| 720x1600 | 2817 → 2303 | -16.6% | -17.3% | -16.3% | -17.8% |
| 1000x1200 | 1797 → 2568 | +29.9% | +36.4% | +43.0% | +42.9% |
| 560x960 | 771 → 1799 | +90.6% | +111% | +124% | +131% |
Request time changes followed token count changes. For 504x1120, both fell sharply; for 560x960, both rose. Token counts stayed unchanged for 640x480, 1024x768, 2000x1500 and 3024x4032, with CUDA changes of -2.8%~+0.8% and CPU changes within noise. For stretching costs, the PR author measured 1024x768 preprocessing time falling from 31.0ms to 25.9ms in an LFM2.5-VL CUDA build.
How to upgrade
In b11774, LFM2 models can be loaded with -hf.
llama-server -hf LiquidAI/LFM2.5-VL-450M-GGUF:F16 --port 8080 &Among sizes with changed layouts, 27,834 had token counts fall by up to 2,048, while 4,092 had increases. Most increases were below 100, but 523 sizes gained 256~1,024 tokens.
The d1-3B runner first downsizes images above 1 megapixel, unlike the reference code, which processes the full image, leaving 6 length mismatches out of 96 questions. Of the 6 changed items, 3 worsened (maximum probability difference 0.019 → 0.029) and 3 improved.
Who this matters to
The earlier PR #27057 changed the tiling decision from side length to pixel area. This update aligns tile content and calculations for grid and preview sizes.
If you run LFM2 models with llama.cpp, upgrade to b11774, compare the same images against Transformers outputs, and recalculate request time budgets based on token count changes for each image size.