After launch coverage on September 30, the Ling-3.1-flash card checked on October 14 listed an MIT license and SGLang/vLLM serving examples. It describes 560B total parameters and 25B active per token.
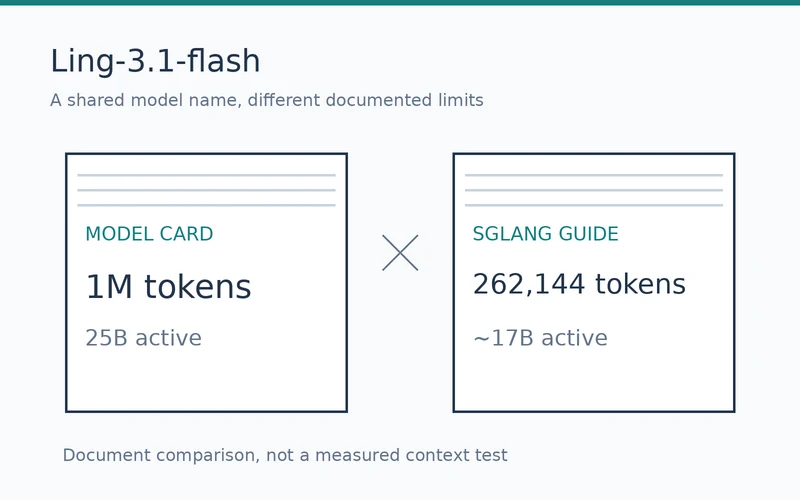
1M versus 262,144 context tokens
The model card lists 1M context tokens, while SGLang's deployment guide specifies 262,144. Their active-parameter counts also differ, at 25B and about 17B. The available documents do not establish whether this reflects counting methods or an incorrect entry.
Architecture and SGLang serving settings
The model combines 63 KDA layers with nine Gated MLA layers, selecting eight of 512 routed experts per token. SGLang documents an FP8 serving image and NEXTN token prediction tailored to this architecture.
For long documents, the limit configured on the actual server matters more than the advertised 1M figure. The published recipes use eight H200 or four GB300 GPUs, so 25B active parameters alone do not establish a small memory requirement.
Artificial Analysis displays an Intelligence Index score of 41 alongside a 'weights unavailable' label. That differs from the MIT-licensed card and its serving examples. The score and the availability status need separate checks.
For self-hosting, check the chosen checkpoint against the server's configured context limit. A 1M-token claim on the card does not demonstrate a working deployment at that length.
The usable scope of Ling-3.1-flash depends on the checkpoint and server configuration agreeing, not the model-card figure alone.