Baidu unveiled Unlimited OCR 2, a document recognition model that parses long documents in one request rather than separate page submissions. Developers can supply entire documents to use cross-page context for tables and text.
1. Refer only to relevant information and reuse page chunks
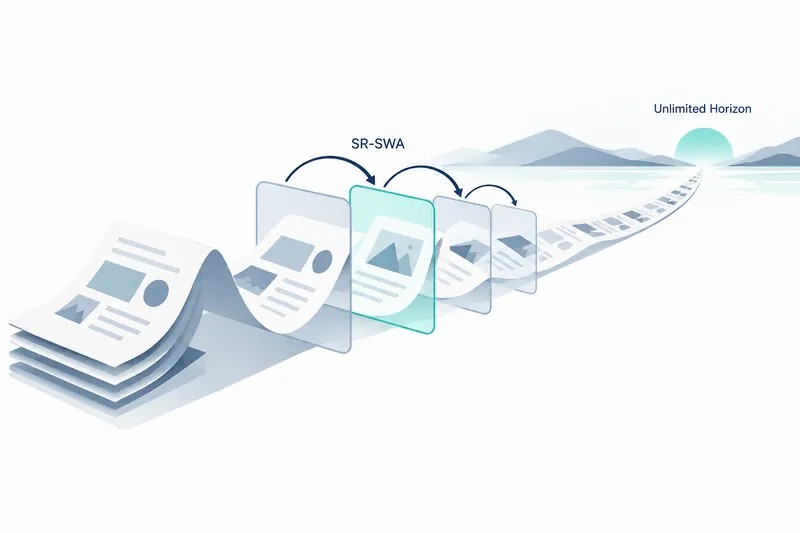
The original Unlimited OCR kept text working memory constant, but revisited every page's visual information at each generation step as documents grew. Sparse Reference Sliding Window Attention (SR-SWA) reduces this burden. Rather than revisiting everything equally, it focuses on selected reference information relevant to the current page.
A separate sequential processing method reduces the burden of keeping the entire document in GPU memory. It processes chunks with overlapping boundary pages, reuses KV caches of prior boundary computations, and releases caches outside the current chunk. It accepts one request but internally retains only the needed chunks, like turning pages in a book.
2. Pass page images in order in a single request
Developers can test quickly with Transformers or use SGLang, which Baidu recommends for serving. Passing multiple page image files in order lets the model parse the entire document in one request using cross-page context.
This is the repository's multipage example.
pages = [f"your_doc/page_{i}.jpg" for i in range(1, 8)]

text, num_tokens = model.infer_multi(tokenizer, image_files=pages,
                                     output_path="output/multi", save_results=True)
Baidu tested it with Python 3.10 and PyTorch 2.13.0.
The tests used Transformers 4.52.1 and an NVIDIA A800 80GB GPU.
The model's raw output is a structured block string distinguishing document elements, not Markdown. The repository's postprocessing tools organize page markers, heading levels, tables, and coordinates into evaluation Markdown.
3. Outscoring comparison models on hundred-page documents
Baidu's MarathonDocBench contains 100 documents of 103–300 pages and about 200,000 layout elements annotated with locations and types. Its overall score assesses text recognition, tables, formulas, reading order, and cross-page structures. Baidu reports 77.06 for Unlimited OCR 2, above the best comparison model, Kimi-K3, at 33.74.
Table: MarathonDocBench overall scores
Conditions: 100 MarathonDocBench documents (103–300 pages), per-model evaluation results in Table 2 of the technical report, as reported by Baidu
Unit: Score (%)
| Model | Overall score (%) |
|---|---|
| Unlimited-OCR 2 | 77.06 |
| Kimi-K3 | 33.74 |
| Gemini-3.8-Flash | 28.61 |
| Qwen-3.8-Flash-Next | 27.83 |
| Gemini-3.1-Pro Preview | 26.97 |
| Qwen3.8-Max | 22.93 |
| Minimax-M3 | 17.97 |
| DeepSeek-4.1-Flash | 12.34 |
| GLM-5.3-Flash | 7.51 |
The key is that this evaluation is rich in sentences and tables spanning pages. Baidu also reports an overall score of 84.59 on MPDocBench, a separate evaluation covering documents of up to 30 pages.
4. Page chunks manage memory; configuration and conversion add operational work
Baidu reports step-by-step decoding speeds on hundred-page documents at 7.0x those of full attention and 5.6x those of the earlier R-SWA reference method. Measurements used Gundam mode, which splits page images into smaller tiles, with a batch size of 3 and 1,024 generated tokens per page.
In the same report's MarathonDocBench measurements, peak KV cache memory per request fell from 47.00GB with standard decoding to 1.77GB with sequential chunking. Baidu reports throughput rising from 360 to 1,315 tokens per second with 16 concurrent requests.
Developers can submit long documents in one request while reducing GPU memory demands. Service integration instead requires tuning page chunk sizes and output budgets to documents, then converting structured output to the required format.
5. Prioritizing long documents over the top single-page score
Baidu reports higher single-page scores for the two comparison models below. This highlights a different selection criterion from long-document processing.
Table: Single-page overall scores
Conditions: OmniDocBench v1.6 evaluation results in Table 3 of the technical report, as reported by Baidu
Unit: Score (%)
| Model | Overall score (%) |
|---|---|
| Unlimited-OCR 2 | 94.02 |
| OvisOCR2 | 96.47 |
| TeleOCR | 96.91 |
Small page chunks lower peak memory but can disrupt context for blocks spanning boundaries, affecting merge quality. The report says sparse attention cannot preserve all document information, limiting document-level understanding such as heading hierarchies.
Unlimited OCR 2 focuses on moving multipage parsing into single-request services by curbing per-step computational burdens as document length grows.