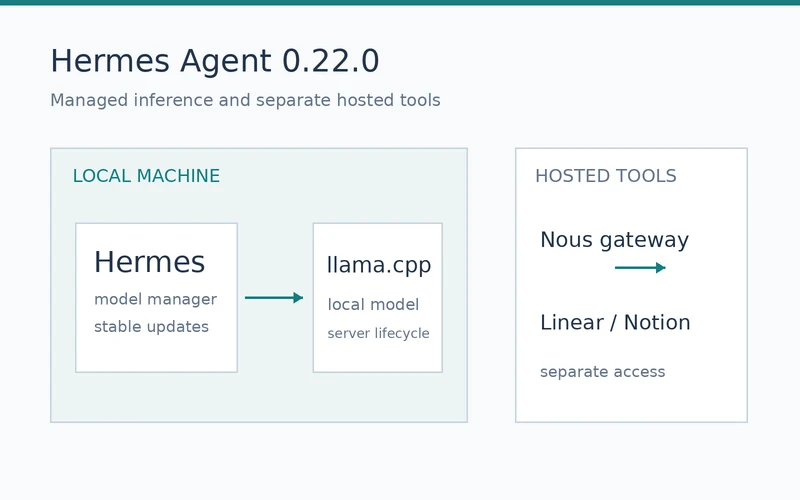
NousResearch released Hermes Agent 0.22.0. It moves local-model setup and software updates into one managed workflow.
Downloading model weights is only part of the job; the inference engine and server still need managing. This release brings those steps together.
Local-model operations and stable updates
Hermes installs llama.cpp and chooses a suitable CPU, CUDA, Metal, Vulkan or ROCm engine. Downloads can resume, and the model server starts and stops with Hermes.
Source installations now follow stable releases by default instead of every commit on main. The package manager checks a new environment before switching, reducing the risk of interrupted updates.
The main gain is less setup and maintenance work, not better model performance. Model recommendations help choose a runnable configuration; they do not guarantee task speed or tool-call quality.
Local inference versus hosted app connections
Choosing a local model does not make the entire workflow offline. Hosted apps such as Linear and Notion connect through the Nous tool gateway.
In the terminal, the command below opens the menu containing Local models. The desktop path is Settings → Providers → Local Models.
hermes modelSetup is easier, but response quality still depends on the selected model and task.
Hermes 0.22.0 simplifies local-model operations without making hosted app connectors local.